LLaDA-Image — 무료 온라인 AI 이미지 생성·편집
브라우저에서 LLaDA-Image로 이미지를 생성하고 참조를 편집하며 이중언어 포스터를 만드세요. 오픈소스 text-to-image와 image-to-image 편집, 그리고 빠른 LLaDA-Image Turbo 경로를 제공합니다.
Showcase media sourced from the public LLaDA-Image repository. This site is independent and is not affiliated with inclusionAI.
Model snapshot
What LLaDA-Image ships
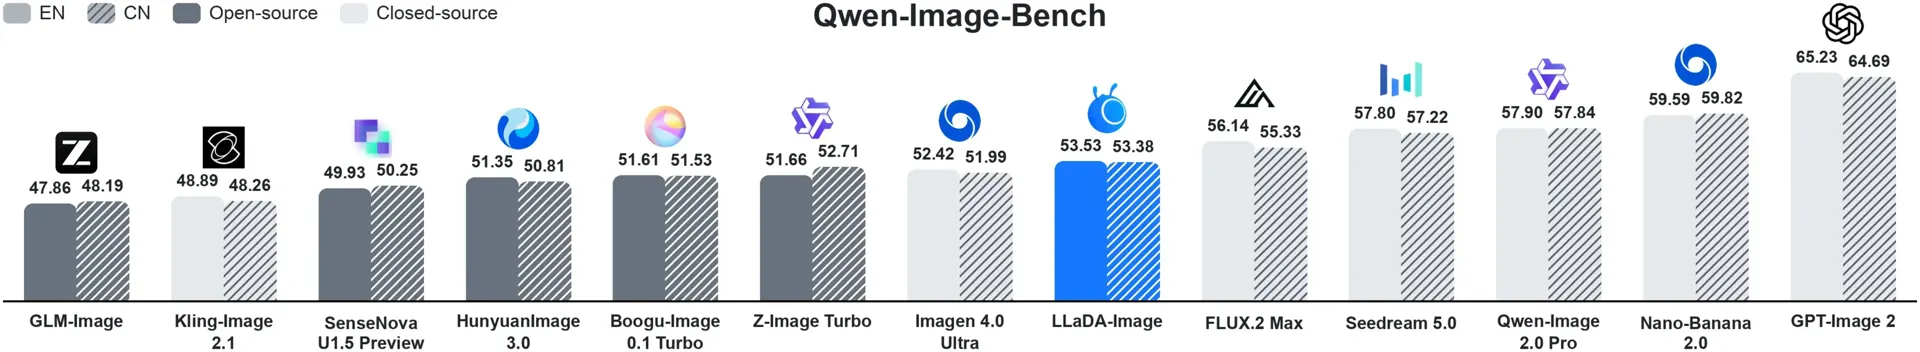
Figures below summarize the public Sep 2026 release notes for the 6B LLaDA-Image family. Live rankings can change.
6B
Parameters
Competitive 6B open unified generation and editing family.
50
Base steps
Recommended sampling for high-fidelity LLaDA-Image Base.
4
Turbo steps
Twin-DMD distilled LLaDA-Image Turbo for 2–4 step speed.
53.5
EN bench
Reported overall Qwen-Image-Bench score (EN 53.53 / ZH 53.38).
Why it matters
One checkpoint for generation and editing
LLaDA-Image is built as a unified diffusion stack — not a separate editing backbone bolted on later.
Unified gen + edit
A single checkpoint covers text-to-image and reference-preserving, instruction-guided editing.
Chinese–English text
Practical poster and layout rendering across bilingual creative briefs.
Instruction editing
Upload a reference and describe the change — keep subject fidelity while updating style or content.
Turbo distilled path
LLaDA-Image Turbo targets fast generation and editing in only a few sampling steps.
Generation modes
Text, VQ, and editing in one API shape
The open Diffusers pipeline supports three practical modes. This workspace mirrors the same intents online.
text
Text-to-image
Prompt-only generation with height/width divisible by 16 for Base and Turbo.
vq
VQ-conditioned
Uses LLaDA2 image VQ tokens from the prompt before diffusion — no input image required.
editing
Image editing
Provide a reference image and an instruction. Editing paths expect dimensions divisible by 32.
Examples
Sample outputs and prompt directions
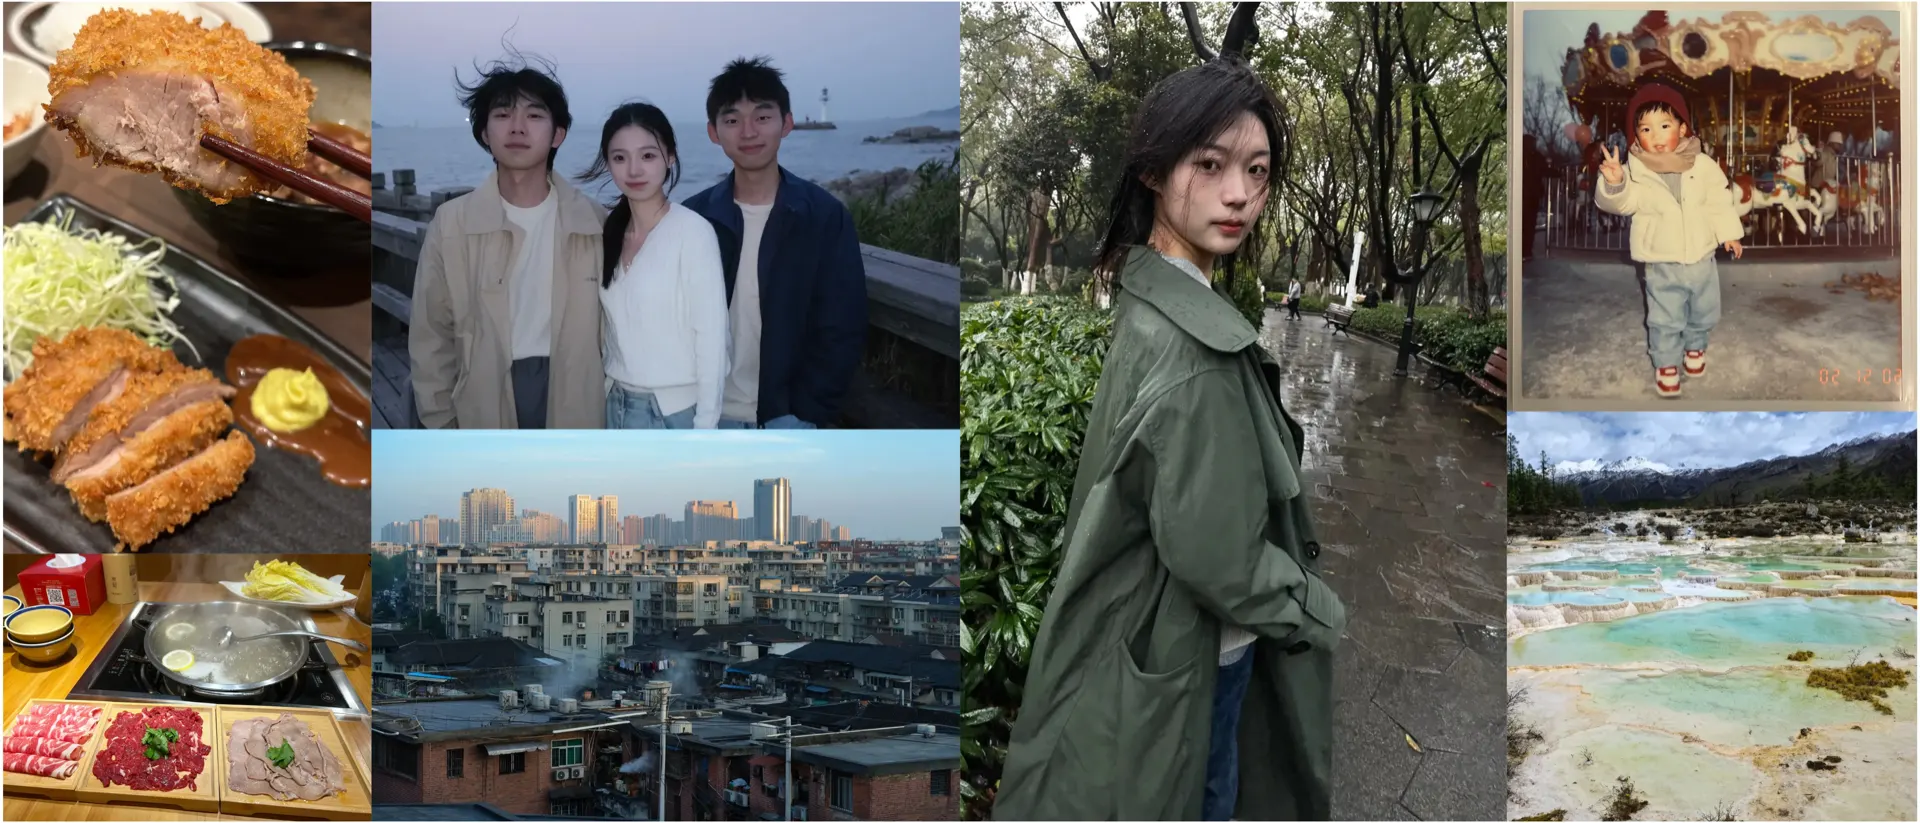
These stills come from the public LLaDA-Image repository showcase assets (not live runs billed on this site). Use them as reference for subject, text-in-image, and edit intent. Credits below match this workspace’s LLaDA-Image / Turbo rate (~10 credits per image).
LLaDA-Image Base
Photoreal product still life with soft window light and crisp materials
~10 credits
LLaDA-Image Turbo
Fast draft of the same still-life brief for layout exploration
~10 credits
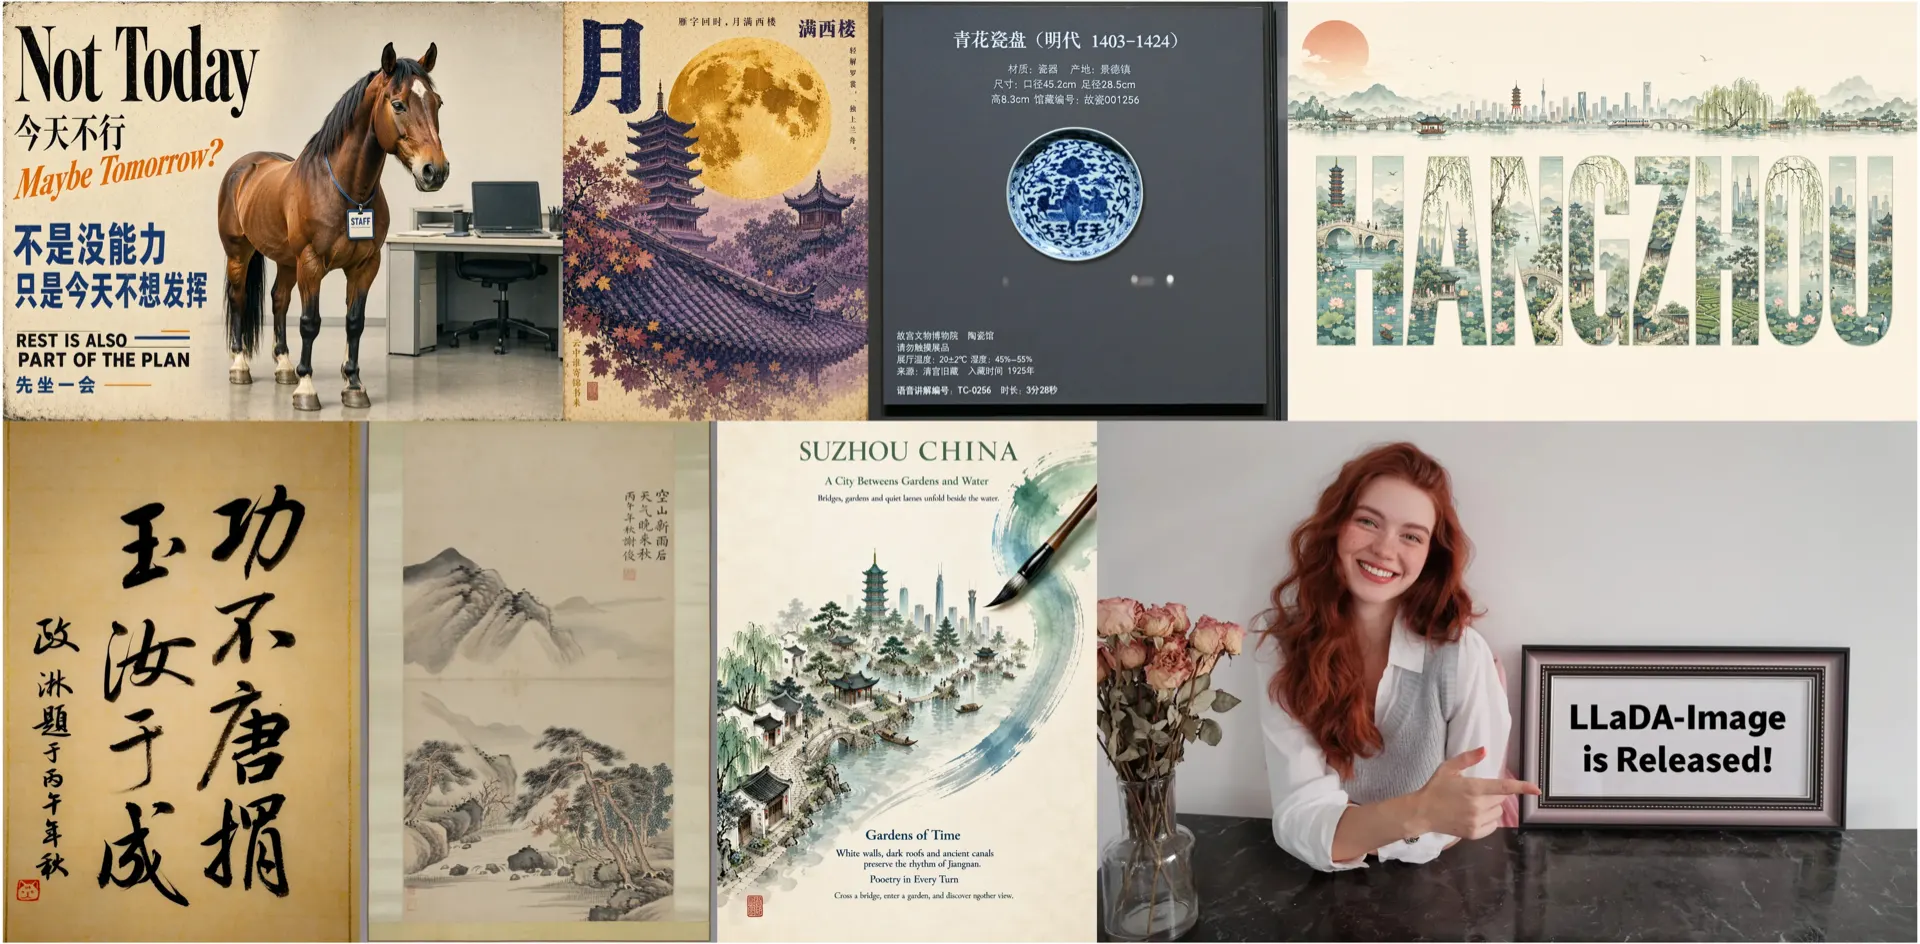
LLaDA-Image Base
Bilingual poster with clear English headline and Chinese subhead
~10 credits
LLaDA-Image Turbo
Quick poster composition pass before refining typography
~10 credits
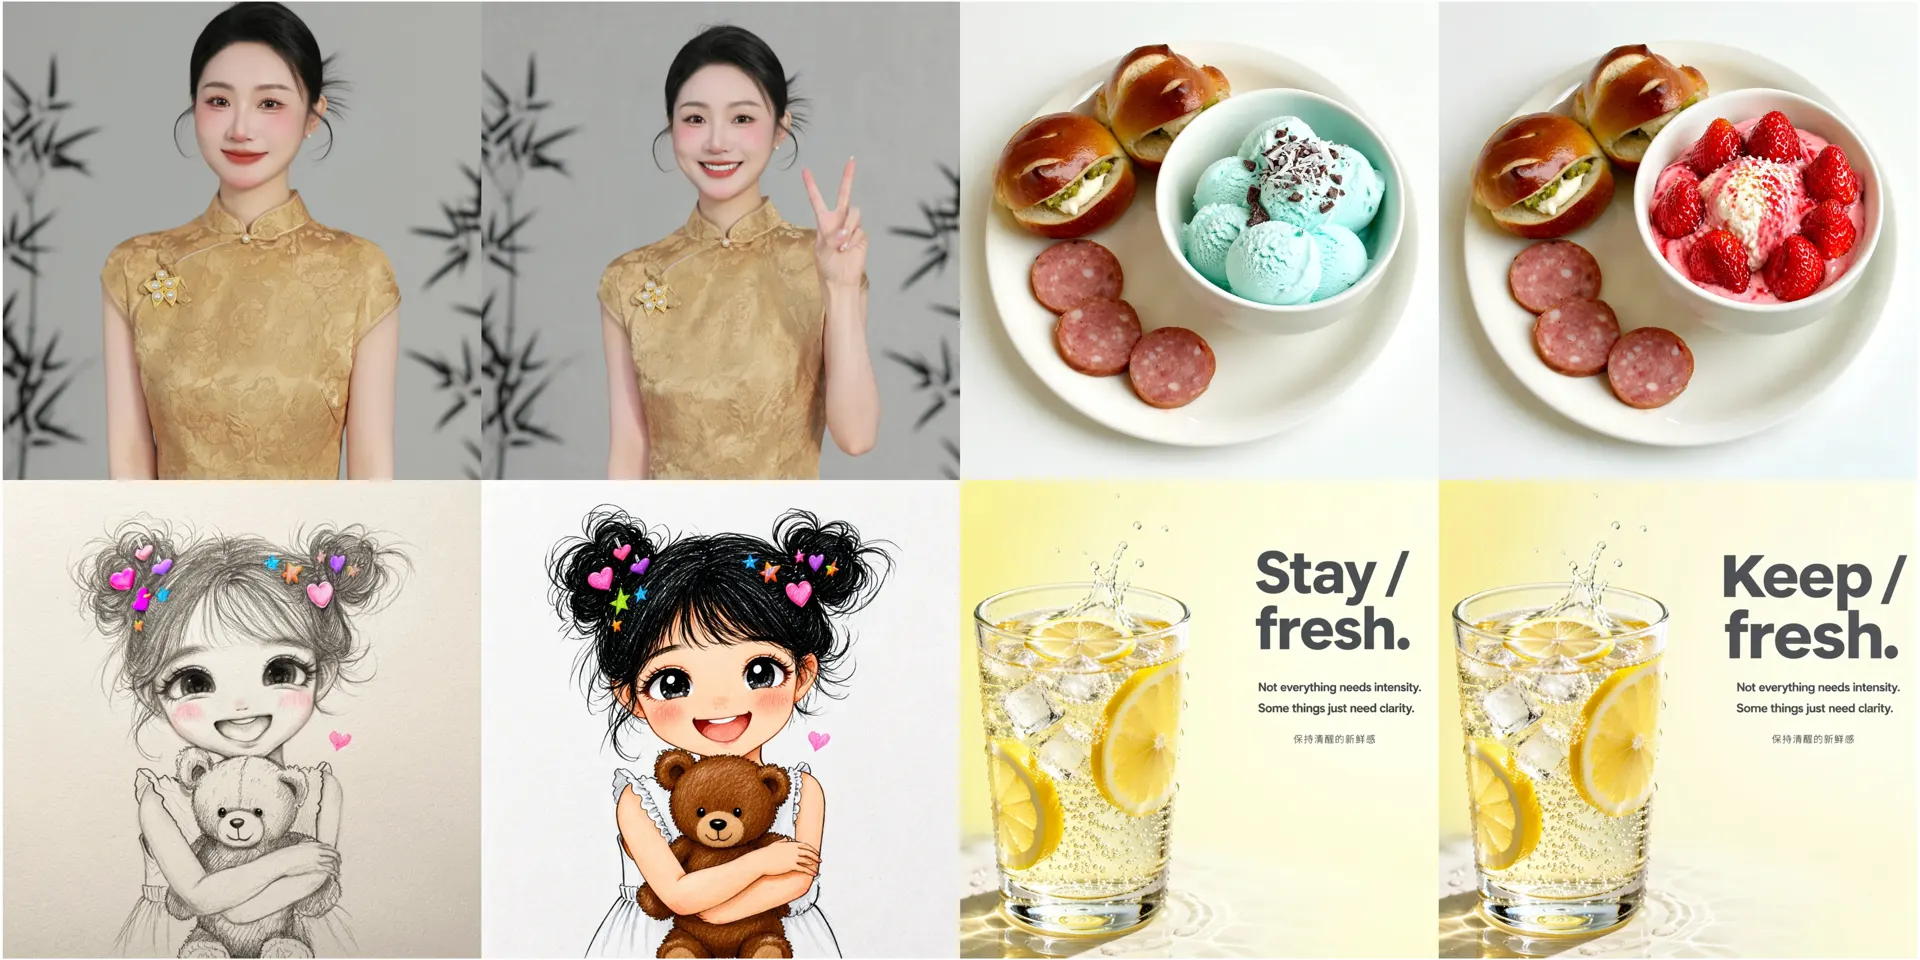
LLaDA-Image Base
Instruction edit: keep subject identity, change only the background
~58+ edit
LLaDA-Image Turbo
Faster edit loop to try alternate backgrounds
~10 edit
Source: public LLaDA-Image repo showcase. Credit figures are this site’s published rates, not measured runtimes.
Evidence
Photoreal, posters, and edits
Official showcase strips highlight the three capabilities users search for after the open release.
Primary sources
Where to verify LLaDA-Image
Prefer the official open-source channels for weights, code, and the paper. This site only provides an independent browser workspace.
FAQ
LLaDA-Image questions
What is LLaDA-Image?
LLaDA-Image is a 6B open-source unified image generation and editing model family from inclusionAI, released with Base (≈50 steps) and Turbo (≈4 steps) checkpoints.
lladaimage.com은 공식 사이트인가요?
아닙니다. LLaDA-Image / llada image 검색 수요를 위한 독립 온라인 워크스페이스입니다. 공식 코드와 가중치는 GitHub, Hugging Face, ModelScope에 있습니다.
What is LLaDA-Image Turbo?
Turbo is the Twin-DMD distilled variant for fast generation and editing in a few sampling steps. Open the Turbo page when you want the speed-oriented path.
Can I edit images as well as generate?
Yes. Upload a reference in the workspace and describe the change. The open model supports instruction-guided editing without a separate editing backbone.
Where do the showcase images come from?
The hero and gallery samples are sourced from the public LLaDA-Image repository assets, credited on-page. Live generations in the tool use this site’s hosted pipeline.
브라우저에서 LLaDA-Image 시도
Start from a prompt or reference image, then switch to Turbo when you need faster iterations.